NOiz AI High Quality AI Speech Generation Platform- ChooseAI Tools
NOiz AI
High-quality AI speech generation platform from TTS to timbre customization
TTS Services
Timbre Cloning & Synthesis
Speech Macromodel
Multilingual Translation Tools
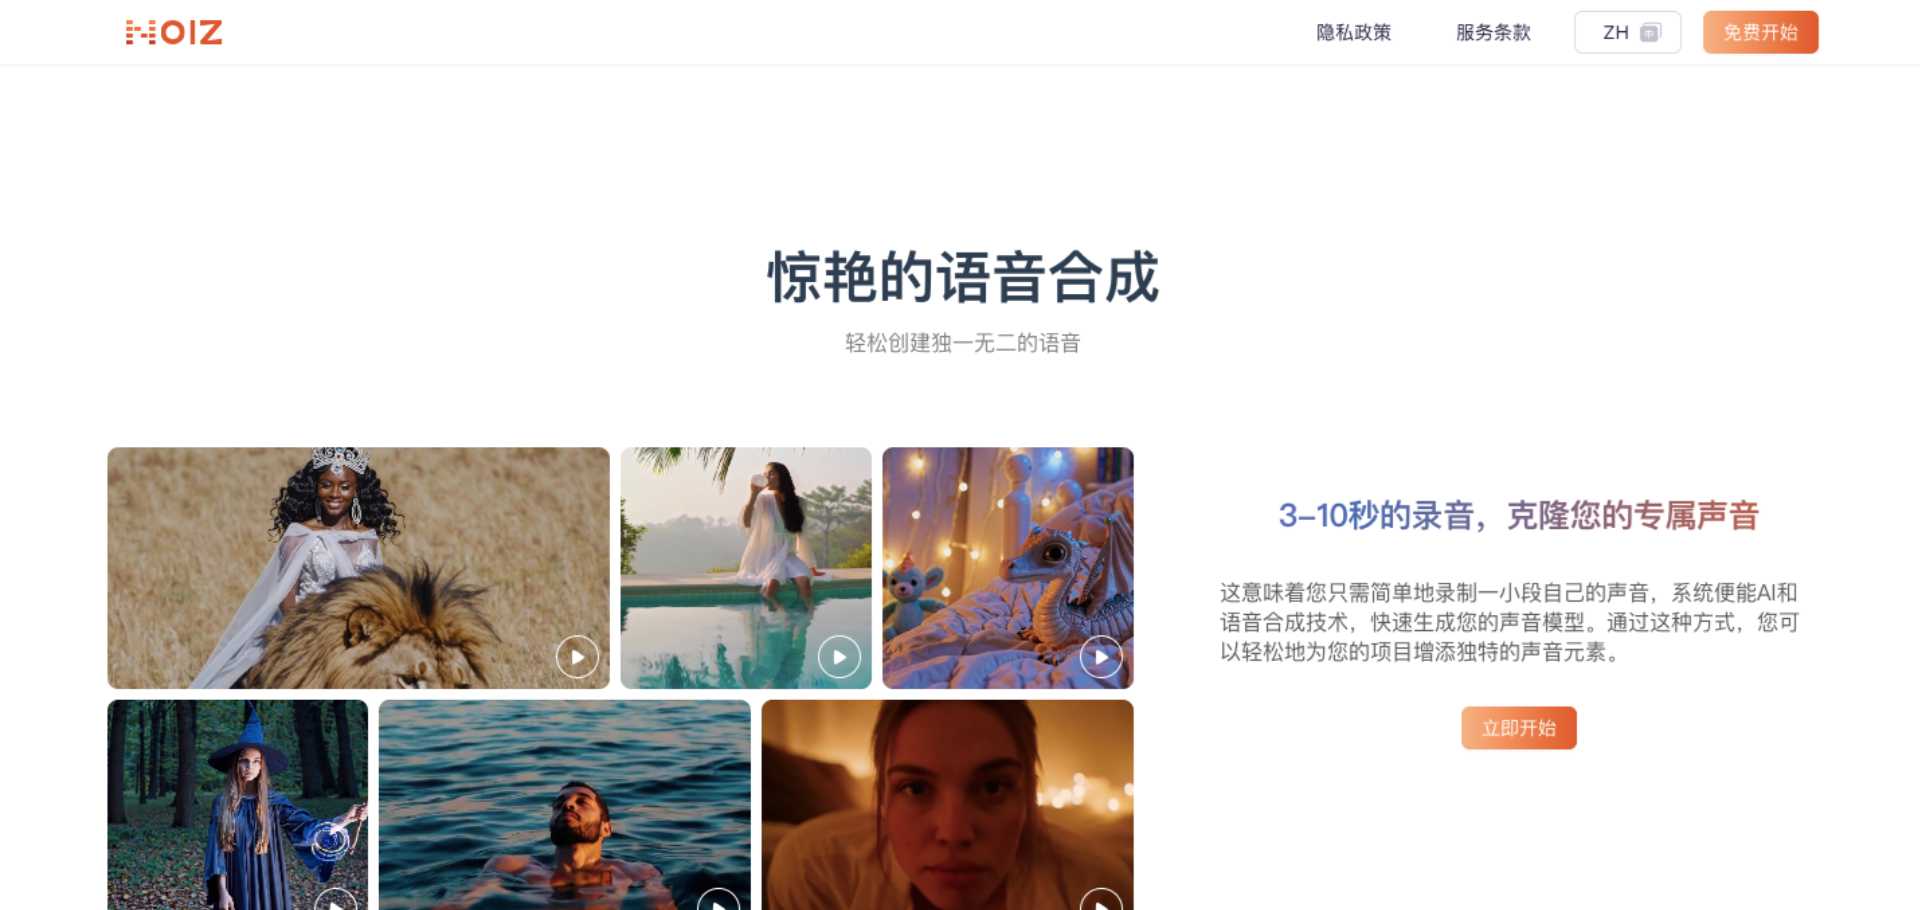
Noiz AI is a multifunctional AI media tool that combines Text To Speech and intelligent summarization. Relying on the self-developed large-scale voice model, its voice module provides high-fidelity, natural and expressive text-to-speech (TTS) service. It has low delay generation, high cost performance and personalized customization capability. It is widely used in content dubbing, timbre cloning, audio and video translation and other scenes. Users can instantly generate voice announcements or deeply customize sound assets that match brand tonality.
Preview
Introduction
functional characteristics
It provides high-fidelity, low-latency text-to-speech (TTS) services that support emotional labeling and intonation parameter adjustment to generate natural, fluent and expressive speech.
Support zero-training sound cloning, only 3 - 10 seconds of audio to reproduce the tone, suitable for personalized dubbing and brand sound asset customization.
Integrated intelligent summarization capability for automatic transcription, segmentation, translation and refinement of audio and video content.
application scenarios
Short Video and self-media content dubbing: Quickly generate multilingual, multi-styled narration or character voice.
Audio and video localization and translation: automatic subtitle generation, voice translation and mouth synchronization, helping content go to sea.
Audio book and story production: support multi-character, multi-emotion switching, adapt long text Text To Speech.
Brand voice asset creation: customize exclusive brand voice through tone cloning for customer service, advertising and other scenarios.
suitable for the croud
Content creators, bloggers of Short Video, podcasters, etc. Individual users who need efficient dubbing tools.
Enterprise users who need multilingual audio and video Media Processing Service, such as educational institutions, film and television teams, cross-border e-commerce, etc.
type of pricing
Free value-added (freemium) model, basic features free to use, advanced features (such as high concurrency, fine tone control, commercial licensing) on a subscription basis.
supported langauges
Support more than 30 languages, including Chinese, English, Japanese, French, German, Spanish, Russian, Arabic and other mainstream and minority languages.
technical highlights
Based on self-developed large-scale speech model, combined with natural language cues to achieve fine-grained voice control (such as gender, accent, speed, emotion).
Text To Speech quality and performance close to the level of real people, in low resource conditions still maintain a high degree of reduction, better than most open source TTS schemes.
usage mode
Direct use through the web platform, no download and installation; desktop and mobile apps will be launched in the future to support offline and batch processing.
update history
December 2025: Launched emoji to command AI dubbing function, supporting triggering specific mood and emotion through emoji.
May 2025: Optimize the zero-sample sound cloning algorithm to improve the accuracy of voice reproduction under 3-second short audio to more than 95%.